
 By Layla Zulfa
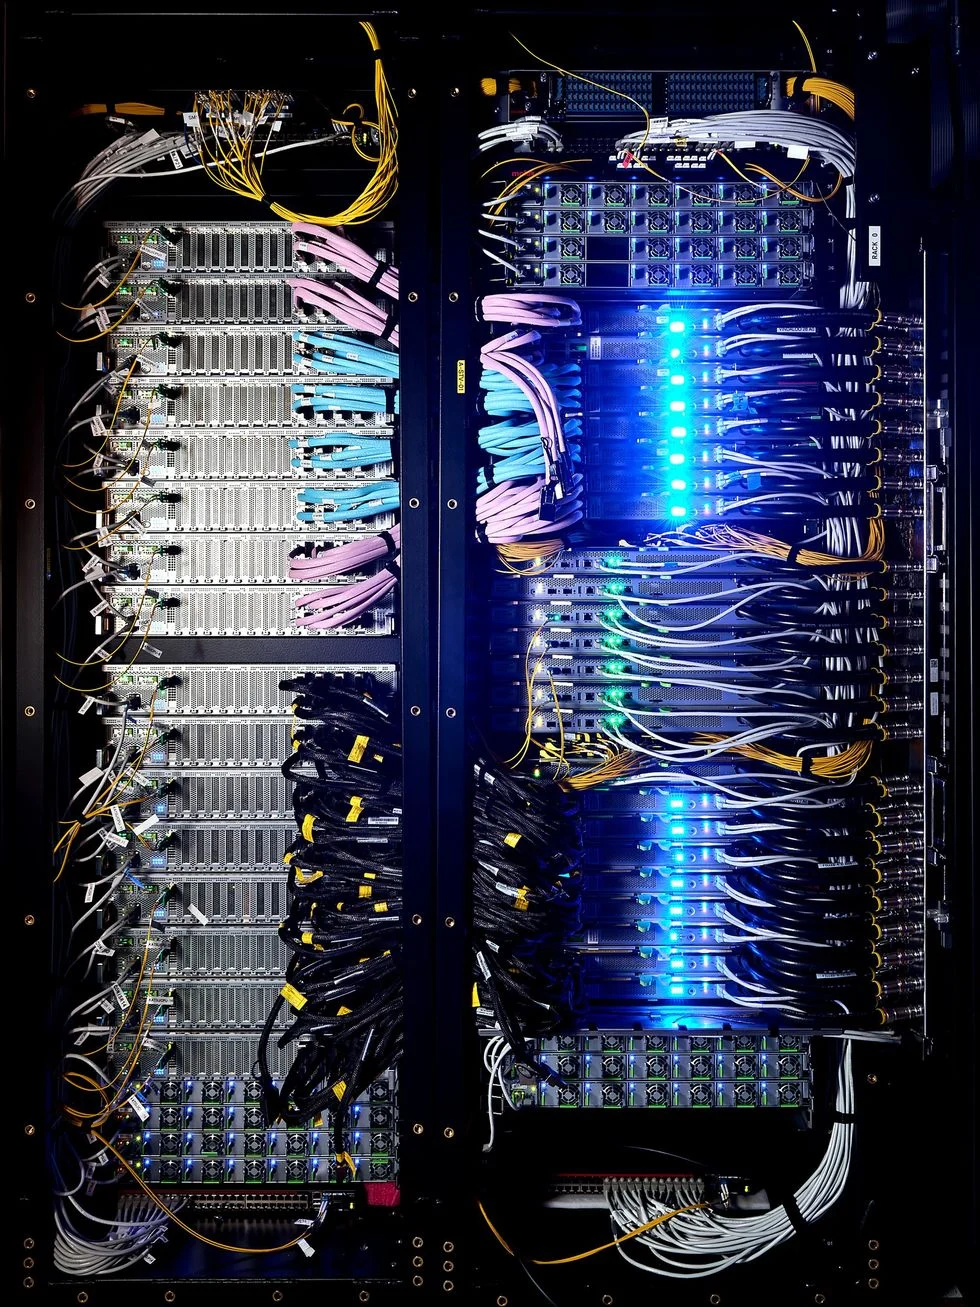
On August 25, the technology landscape shifted as OpenAI officially unveiled Jalapeño, its inaugural custom AI accelerator chip. More than just a piece of hardware, Jalapeño represents a fundamental pivot in how the world’s most advanced processors are conceived, simulated, and manufactured. By leveraging its own frontier large language models (LLMs) to streamline the design cycle, OpenAI has achieved a development velocity that industry veterans describe as “best-in-class,” signaling a potential paradigm shift in semiconductor engineering.
The Technical Specs: Pushing the Boundaries of Inference
Jalapeño enters the market as a high-performance beast designed specifically to meet the insatiable demands of OpenAI’s massive inference fleet. According to benchmarks provided by the company, the chip delivers a staggering 13.4 petaflops of 4-bit compute. To feed this processing core, the architecture integrates 232 gigabytes of high-bandwidth memory, utilizing an interface capable of an industry-leading 15.4 terabytes per second.
The most critical metric for OpenAI is end-to-end latency—the time elapsed from the moment a user submits a prompt to the generation of the final token. In comparative tests against Nvidia’s GB300, the industry standard that currently powers much of OpenAI’s infrastructure, Jalapeño demonstrated a 3.6x improvement in latency, all while maintaining a more efficient power-consumption profile. While the industry waits to see how these benchmarks scale when thousands of these chips are deployed in production, the initial results suggest that OpenAI has successfully built a "custom-fit" solution that avoids the general-purpose overhead of off-the-shelf alternatives.
A Chronology of Rapid Innovation
The most striking aspect of the Jalapeño project is its timeline. The project moved from an abstract architectural concept to the delivery of functional silicon in under 20 months. Perhaps most impressively, only nine months elapsed between the finalization of the Register-Transfer Level (RTL) code—the bedrock of the chip’s logic—and the “tape-out” phase, when the design was sent to the foundry for manufacturing.
- October 2024: The project formally commences with a lean team of fewer than 100 engineers.
- April 2025: OpenAI integrates early versions of its o3 reasoning models to assist in code synthesis and verification.
- May 2026: The first batch of silicon arrives from the foundry, triggering an intensive 40-hour AI-led optimization sprint.
- August 2026: Official unveiling of the Jalapeño architecture at the IEEE Hot Chips conference.
This rapid-fire cadence was facilitated by a strategic division of labor. OpenAI focused on the “front-end” of the process—system architecture, memory hierarchies, and networking—while partnering with industry titan Broadcom to handle the complex “physical design” and manufacturing implementation.
Supporting Data: The AI-Driven Workflow
The secret to OpenAI’s speed lies in its proprietary workflow, which centers on Accelerated Hardware Synthesis (XLS). Originally developed at Google, XLS allows engineers to design hardware using high-level programming languages like C++ and DSLX (a Rust-inspired domain-specific language) rather than traditional, cumbersome hardware description languages.
OpenAI’s engineers, led by technical staff member Chris Leary, discovered that their LLMs possessed a natural affinity for these software-centric design environments. By treating chip design as a code-generation task, the team was able to offload significant portions of the logic writing to AI.
The power of this approach was most evident during the post-silicon phase. When the first chips arrived in May, the team tasked their internal models with optimizing the software kernel for the chip. On the DeepSeek multi-head latent attention kernel, the AI iteratively refined the software performance, boosting it from a mere 0.31 percent of the chip’s theoretical ceiling to a robust 88.94 percent in just 40 hours. This capability allows OpenAI to bypass months of manual performance tuning, effectively "unlocking" the chip’s potential after it has already left the factory.
Official Responses and Expert Analysis
Richard Ho, OpenAI’s Vice President of Hardware, describes the role of AI not as a replacement for human intellect, but as an amplifier. “The models are giving superpowers to our engineers,” Ho remarked during the project’s debut. “Our engineers are still driving the work. They’re still the final arbiter of what’s going on. But they can do things a lot faster. They can explore a lot more paths.”
However, the industry reaction is one of cautious, albeit impressed, evaluation. David Chin and Ravi Krishna, co-founders of the agentic chip design startup Verkor.io, noted that while the schedule is “quite credible,” it was heavily bolstered by the manufacturing expertise of Broadcom.

Andrew Kahng, a distinguished professor at UC San Diego and a veteran of design automation, noted that the move to AI-assisted high-level synthesis is a logical evolution. "I see this as a generally useful workflow," Kahng observed, "and it’s one that ‘has legs’ going into the future."
Ankur Srivastava, director of the semiconductor initiative at the University of Maryland, pointed out that while automation in chip design is decades old, the linguistic understanding of LLMs allows them to bridge the gap between human intent and machine execution in ways previous tools could not.
Implications for the Semiconductor Industry
The success of Jalapeño has profound implications for the future of the silicon industry. It suggests that the barrier to entry for designing frontier-grade AI hardware is dropping. By utilizing small, highly skilled teams augmented by "agentic" AI loops, companies can iterate faster, test more architectural variables, and reduce the time-to-market for specialized AI silicon.
1. The Death of the "Slow" Design Cycle
The traditional multi-year development cycle for new chips may soon be viewed as a relic of the past. As LLMs become more deeply integrated into commercial EDA (Electronic Design Automation) tools, the ability to generate, verify, and optimize RTL will become a standard competitive advantage.
2. The Rise of "Agentic" Backend Design
While the Jalapeño project was largely focused on the front-end, experts believe the next wave of AI will revolutionize the backend—routing, clock distribution, and power management. OpenAI has already hinted that its second-generation chip development is incorporating AI in verification and physical design, including automated waveform manipulation to debug hardware failures in real-time.
3. The Future of Commercial Models
OpenAI’s work with Jalapeño serves as a "dogfooding" experiment for its future commercial models. The techniques used to design the chip are being distilled into models like GPT-6 Astra, which will eventually be available to other enterprises. This means that the "superpowers" currently exclusive to OpenAI’s hardware team could soon be available to any startup with the ambition to design its own specialized silicon.
Conclusion: A New Era of Co-Design
Despite the excitement, both Ho and Leary are quick to temper expectations. They argue that we are far from "push-button" chip design where an AI builds a frontier processor from scratch. The human engineer remains the essential architect, providing the vision, the constraints, and the final validation.
"We’re not saying that anyone can come and just build state-of-the-art, frontier AI/ML accelerator chips using just our tools," Ho clarified. "We are saying there are very specific ways to be better at the process, focusing on small teams and fast timelines to reach quality results."
As OpenAI prepares for its second and third-generation designs, the "Jalapeño" project stands as a clear proof-of-concept. It is a milestone that marks the transition from chips designed by humans to chips designed with the assistance of the very intelligence they are intended to run. In the race to build the next generation of AI infrastructure, the fastest runner may not be the one with the biggest team, but the one with the best-integrated AI design workflow.
 Nana
 Iffa Jayyana
