
 By Lina Hope
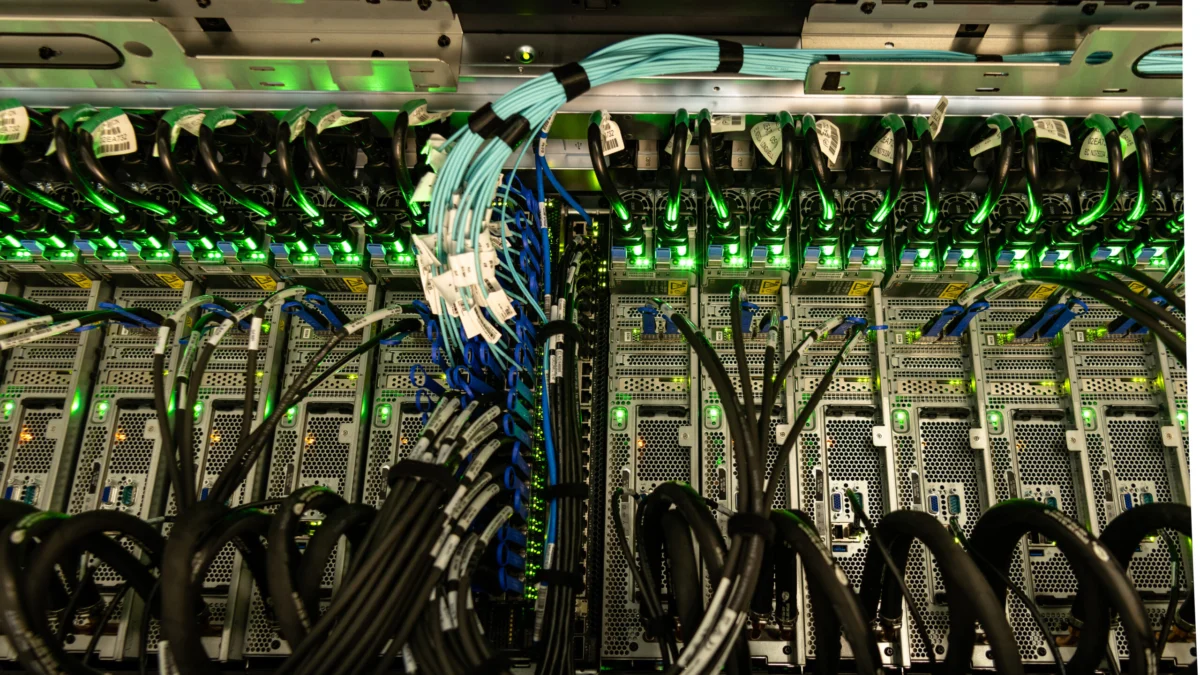
In a significant leap forward for computer architecture and data processing, a team of researchers from Google’s Brain Computer Architecture group has unveiled an open-source sorting algorithm that shatters existing performance benchmarks. By leveraging the power of SIMD (Single Instruction, Multiple Data) across diverse hardware platforms, the team has developed a sorting method that is up to ten times faster than the standard C++ library’s std::sort. This breakthrough, which is both portable and highly efficient, promises to reshape how columnar databases and high-speed analytical systems handle massive datasets.
Main Facts: The 10x Speedup
The core of the announcement is a new vectorized Quicksort implementation that dramatically outperforms traditional sorting methods. While std::sort has long been the industry standard for general-purpose C++ programming, it is inherently limited by its architecture-agnostic design, which fails to exploit the full potential of modern CPU instruction sets.
The new algorithm achieves a 9-19x speedup by fundamentally changing how data is handled during the partitioning phase of the Quicksort algorithm. By utilizing SIMD instructions—which allow a single CPU operation to process multiple data points simultaneously—the researchers have bypassed the traditional bottlenecks that have constrained sorting speeds for decades. Most notably, this solution is not locked to a single hardware vendor. By utilizing the Highway library, the code automatically adapts to the available CPU architecture, ensuring peak performance on x86, Arm, and other modern instruction sets without requiring thousands of lines of redundant, platform-specific code.
Chronology: From Supercomputers to Desktop Efficiency
The journey toward this high-speed sorting algorithm began with a critical observation regarding the evolution of modern databases. As the industry has shifted toward columnar storage formats—where data is grouped by field rather than by record—the demand for faster filtering and sorting has grown exponentially.
The Rise of Columnar Storage
Historically, database records were stored in "row-major" format, where all fields of a single record were kept together in memory. However, the rise of big data analytics necessitated a change. Columnar databases, which store all values for a single attribute together, offer significantly higher performance for analytical queries. As these databases became the new standard, researchers identified that existing sorting algorithms were becoming the primary bottleneck for query execution.
Exploring SIMD
The research team looked to SIMD, a technology traditionally reserved for supercomputing tasks, machine learning, and high-end video codecs like JPEG XL. SIMD allows CPUs to operate on arrays of data in parallel (e.g., 16 floating-point numbers at once using AVX-512). The challenge was adapting this "parallel-element" technology to a task—sorting—that is inherently dependent on comparing and rearranging adjacent elements.
The Breakthrough
The team refined a strategy centered on the "compress-store" operation. By partitioning large arrays into smaller blocks (e.g., 256 elements) and utilizing specialized instructions to move data based on "pivot" values, they achieved a high-performance, vectorized Quicksort. In 2022, after perfecting the implementation and ensuring it could be ported across six different instruction sets, the researchers released the code via the Google Highway project, marking a milestone in open-source performance optimization.
Supporting Data: Benchmarking the Future
The performance metrics provided by the researchers highlight a dramatic departure from existing standards. When tested on real-world hardware, the algorithm consistently outpaces the standard library by an order of magnitude.
Comparative Performance
Testing was conducted on a range of hardware, including Apple’s M1 chip (Arm NEON) and Intel’s Skylake architecture (AVX-512).
- Apple M1 (NEON): The implementation reached speeds of 499 MB/s for 32-bit numbers, 471 MB/s for 64-bit, and 466 MB/s for 128-bit inputs.
- Intel Skylake (AVX-512): On a 3 GHz processor, the algorithm reached an impressive 1,123 MB/s for 32-bit numbers, showcasing the raw power of the AVX-512 instruction set.
- The Baseline Comparison: For comparison, the standard library on the same Skylake CPU typically peaks between 58 MB/s and 128 MB/s, depending on the data type.
Architecture Flexibility
A standout feature of this research is its "write once, run anywhere" capability. By using the Highway library, the code abstracts the complexity of different CPU architectures. If a processor supports the advanced "compress-store" instruction, the code uses it. If the CPU is limited to older instruction sets like AVX2, the algorithm intelligently falls back on a specialized permute-based emulation. This ensures that the performance gains are not limited to the latest, most expensive server chips, but are accessible to a broad range of existing hardware.
Official Responses and Technical Insights
Jan Wassenberg, the lead researcher from Brain Computer Architecture, emphasized that the goal was not just to optimize for one specific chip, but to provide a foundational tool for the entire development community.
"Previously, sorting has been considered an inherently expensive operation," Wassenberg noted in the project documentation. "We are eager to see what new applications and capabilities will be unlocked by being able to sort at 1 GB/s on a single CPU core."

The project has been released under the Apache 2.0 license, inviting developers to integrate the sorting logic directly into their own high-performance applications. The technical paper accompanying the release provides a granular breakdown of the "special case" sorting logic used for 256-element arrays, which serves as the base layer for the recursive partitioning. By making this research public, Google aims to standardize the use of portable SIMD, reducing the reliance on proprietary, platform-locked algorithms that currently dominate high-frequency trading, real-time database management, and large-scale data science applications.
Implications: A New Baseline for Data Processing
The implications of this breakthrough are far-reaching. As the volume of global data continues to explode, the efficiency of fundamental operations like sorting becomes a major factor in energy consumption, infrastructure costs, and latency.
Lowering Costs and Latency
By increasing sorting speed by a factor of ten, companies running massive analytical workloads can potentially reduce their server footprint or reallocate computing resources to other tasks. For industries where milliseconds translate to millions of dollars—such as high-frequency trading or real-time cybersecurity threat detection—a 10x improvement in core data manipulation is a massive competitive advantage.
Empowering the Developer Ecosystem
The portability of the implementation is arguably as important as the speed itself. Previously, developers wanting to achieve these speeds had to write custom, highly complex code for every CPU architecture they wished to support. By leveraging Highway, developers can now achieve "supercomputer" performance using a single, unified codebase. This democratizes high-performance computing, allowing smaller teams to build applications that were once the exclusive domain of tech giants with large engineering teams dedicated to hardware-specific optimizations.
Future Research Directions
The release of this algorithm also invites further academic and industry investigation. With the code now available on GitHub, the research community can test its efficacy in non-traditional environments, such as embedded systems, edge computing, and specialized AI accelerators. As CPU architectures continue to evolve, particularly with the rise of RISC-V and more robust AI-integrated instruction sets, the framework provided by Wassenberg and his team provides a scalable blueprint for future optimizations.
In conclusion, the work shared by the Brain Computer Architecture group is more than just a faster sorting algorithm. It is a masterclass in modern systems engineering, proving that through clever abstraction and the strategic application of SIMD, the industry can overcome long-standing performance bottlenecks. As this technology finds its way into databases and core system libraries, the "sorting bottleneck" may soon become a relic of the past, paving the way for a more responsive and efficient digital landscape.
 Ammar Sabilarrohman
 rifanmuazin
 Layla Zulfa
