SEATTLE — In a move set to reshape enterprise data architectures, Amazon Web Services (AWS) has officially announced the general availability of AWS Glue 6.0. The latest iteration of the tech giant’s serverless data integration and ETL (Extract, Transform, Load) service introduces a striking 30% price reduction compared to previous versions, alongside native, end-to-end support for Apache Iceberg v3.
Built upon a thoroughly modernized runtime stack featuring Apache Spark 4.1, Python 3.13, and Scala 2.13, AWS Glue 6.0 promises significantly accelerated performance, enhanced developer ergonomics, and groundbreaking capabilities for handling semi-structured data at scale. Industry analysts view the release as a aggressive play by AWS to consolidate its dominance in serverless analytics while easing the financial burden on data-driven enterprises grappling with exponential data growth.
Main Facts: What’s New in AWS Glue 6.0?
AWS Glue 6.0 is not merely a routine version bump; it is a foundational overhaul designed to meet the demands of modern data lakes and real-time streaming architectures.
Significant Cost Savings: AWS has slashed pricing by 30% across the board for Glue 6.0 workloads, lowering the barrier of entry for resource-intensive data processing pipelines.
Apache Iceberg v3 Integration: Built on Iceberg 1.11.0, Glue 6.0 delivers the most complete Iceberg v3 implementation available on any fully serverless managed Spark service.
The VARIANT Data Type: The headline feature of the release is the introduction of the VARIANT data type complete with shredding support. This innovation allows organizations to store and query complex JSON, log files, and event streams natively without flattening schemas.
Modernized Runtime Engine: Under the hood, the service leverages Apache Spark 4.1, Python 3.13, and Scala 2.13, boosting execution speeds and maximizing the throughput of PySpark applications.
Low-Latency Streaming: The architecture now enables real-time data streaming capabilities operating with single-digit millisecond latency.
Chronology: The Evolution Leading to Glue 6.0
To understand the magnitude of AWS Glue 6.0, it is helpful to trace the evolution of AWS’s serverless data services over recent years:
The Early Era of Managed ETL: AWS Glue launched as a serverless alternative to managing traditional Hadoop and Spark clusters on Amazon EMR. Early versions focused primarily on lowering the operational overhead of provisioning infrastructure for data cataloging and basic batch ETL tasks.
The Rise of Open Table Formats: As data lakes matured, the industry shifted rapidly toward open table formats like Apache Hudi, Delta Lake, and Apache Iceberg. AWS responded by gradually integrating transactional data lake capabilities into Glue, allowing users to perform ACID transactions on object storage.
The Push for Performance and Cost Optimization: With macroeconomic pressures compelling enterprises to scrutinize cloud spending, AWS faced mounting demands to optimize both the performance and pricing models of its analytics portfolio.
The Spark 4.1 and Iceberg v3 Convergence: The culmination of these industry trends led to the development of Glue 6.0. By aligning with Apache Spark 4.1 and the finalized Iceberg v3 specifications, AWS has bridged the gap between raw data ingestion and ultra-fast, structured querying.
Supporting Data and Technical Deep Dive
The architectural enhancements in AWS Glue 6.0 target some of the most persistent bottlenecks in big data engineering: schema rigidity and query performance on semi-structured data.
The Power of VARIANT Shredding
Traditionally, data engineers processing semi-structured data (such as nested JSON objects or dynamic web logs) faced a difficult choice: flatten the schema (leading to massive data duplication and wide, sparse tables) or store the data as strings and parse it on the fly (resulting in abysmal query performance).
AWS Glue 6.0 solves this dilemma with the VARIANT data type and automated shredding support. By storing semi-structured payloads in an optimized binary format, the query engine can prune and read only the specific nested fields requested by a query. According to initial benchmarks, this approach yields dramatically faster read performance compared to legacy string-column approaches—all without custom parsing code or pipeline breakage when upstream schema evolution occurs.
Seamless Upgrades and Backward Compatibility
A frequent pain point during major runtime updates is the engineering overhead required to migrate existing pipelines. AWS has structured Glue 6.0 to minimize friction:
No API changes are required to adopt the new version.
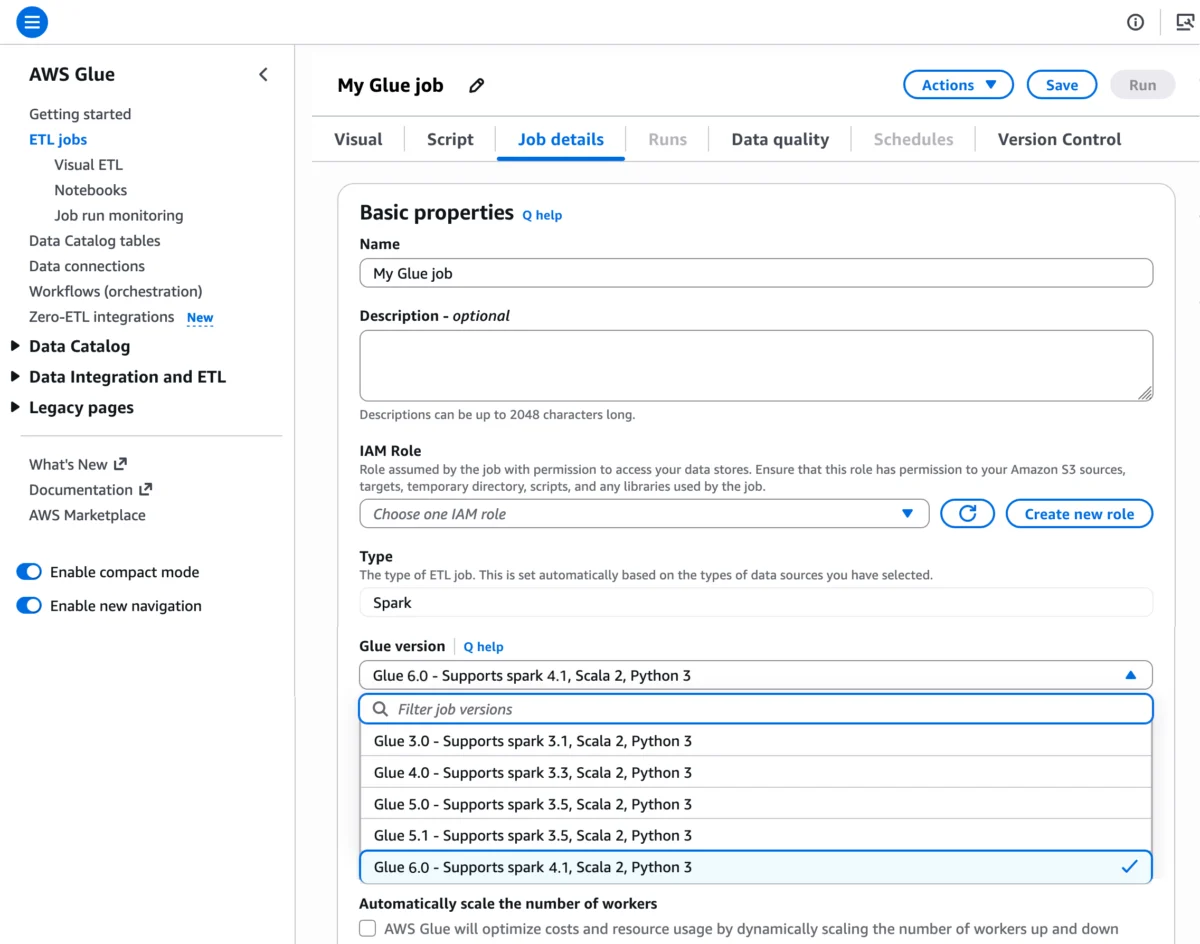
Data teams can provision Glue 6.0 simply by updating the --glue-version parameter in the create-job or update-job APIs via the AWS CLI, AWS SDKs, or AWS Glue Studio.
For legacy jobs, AWS provides an automated Spark upgrade agent within Glue Studio to assist developers in seamlessly transitioning codebases to the Spark 4.1 runtime.
Official Responses and Strategic Implications
Industry leaders and cloud architects have welcomed the announcement, highlighting how the combination of a 30% price drop and advanced Iceberg v3 support alters the competitive landscape.
"With AWS Glue 6.0, Amazon is directly addressing two of the most critical pain points for data engineering teams: ballooning cloud infrastructure costs and the friction of managing semi-structured data," noted a prominent enterprise data architect. "Bringing a complete Iceberg v3 implementation into a serverless Spark environment—while simultaneously reducing prices by nearly a third—sets a new benchmark for managed data services."
Economic Impact on Enterprise Data Lakes
For organizations processing petabytes of data daily, the 30% reduction in compute pricing translates into substantial annual savings. When coupled with the efficiency gains of Apache Spark 4.1 and optimized Iceberg table maintenance, data teams can achieve higher throughput while consuming fewer compute hours.
Furthermore, the simplified pricing model for the AWS Glue Data Catalog—where the first million objects stored and the first million accesses remain free—continues to make the service an attractive central registry for enterprise metadata.
Looking Ahead: Getting Started with AWS Glue 6.0
AWS Glue 6.0 is generally available today across all commercial AWS Regions where AWS Glue operates. Developers and data engineers can begin experimenting with the new features immediately through the AWS Glue Studio console by selecting "Glue 6.0 – Supports Spark 4.1, Scala 2, Python 3" under the Job Details tab.
For notebook users, interactive sessions in Amazon SageMaker Unified Studio or Jupyter notebooks can be initiated by setting %glue_version 6.0 in the session magic commands.
As enterprises increasingly adopt modern data lakehouse architectures built on Apache Iceberg, AWS Glue 6.0 positions itself as a robust, cost-effective engine capable of bridging batch processing, real-time streaming, and complex semi-structured data workflows under a single serverless umbrella.

 By Azzam Bilal Chamdy

 Siti Muinah
 Reynand Wu
 Jia Lissa
